

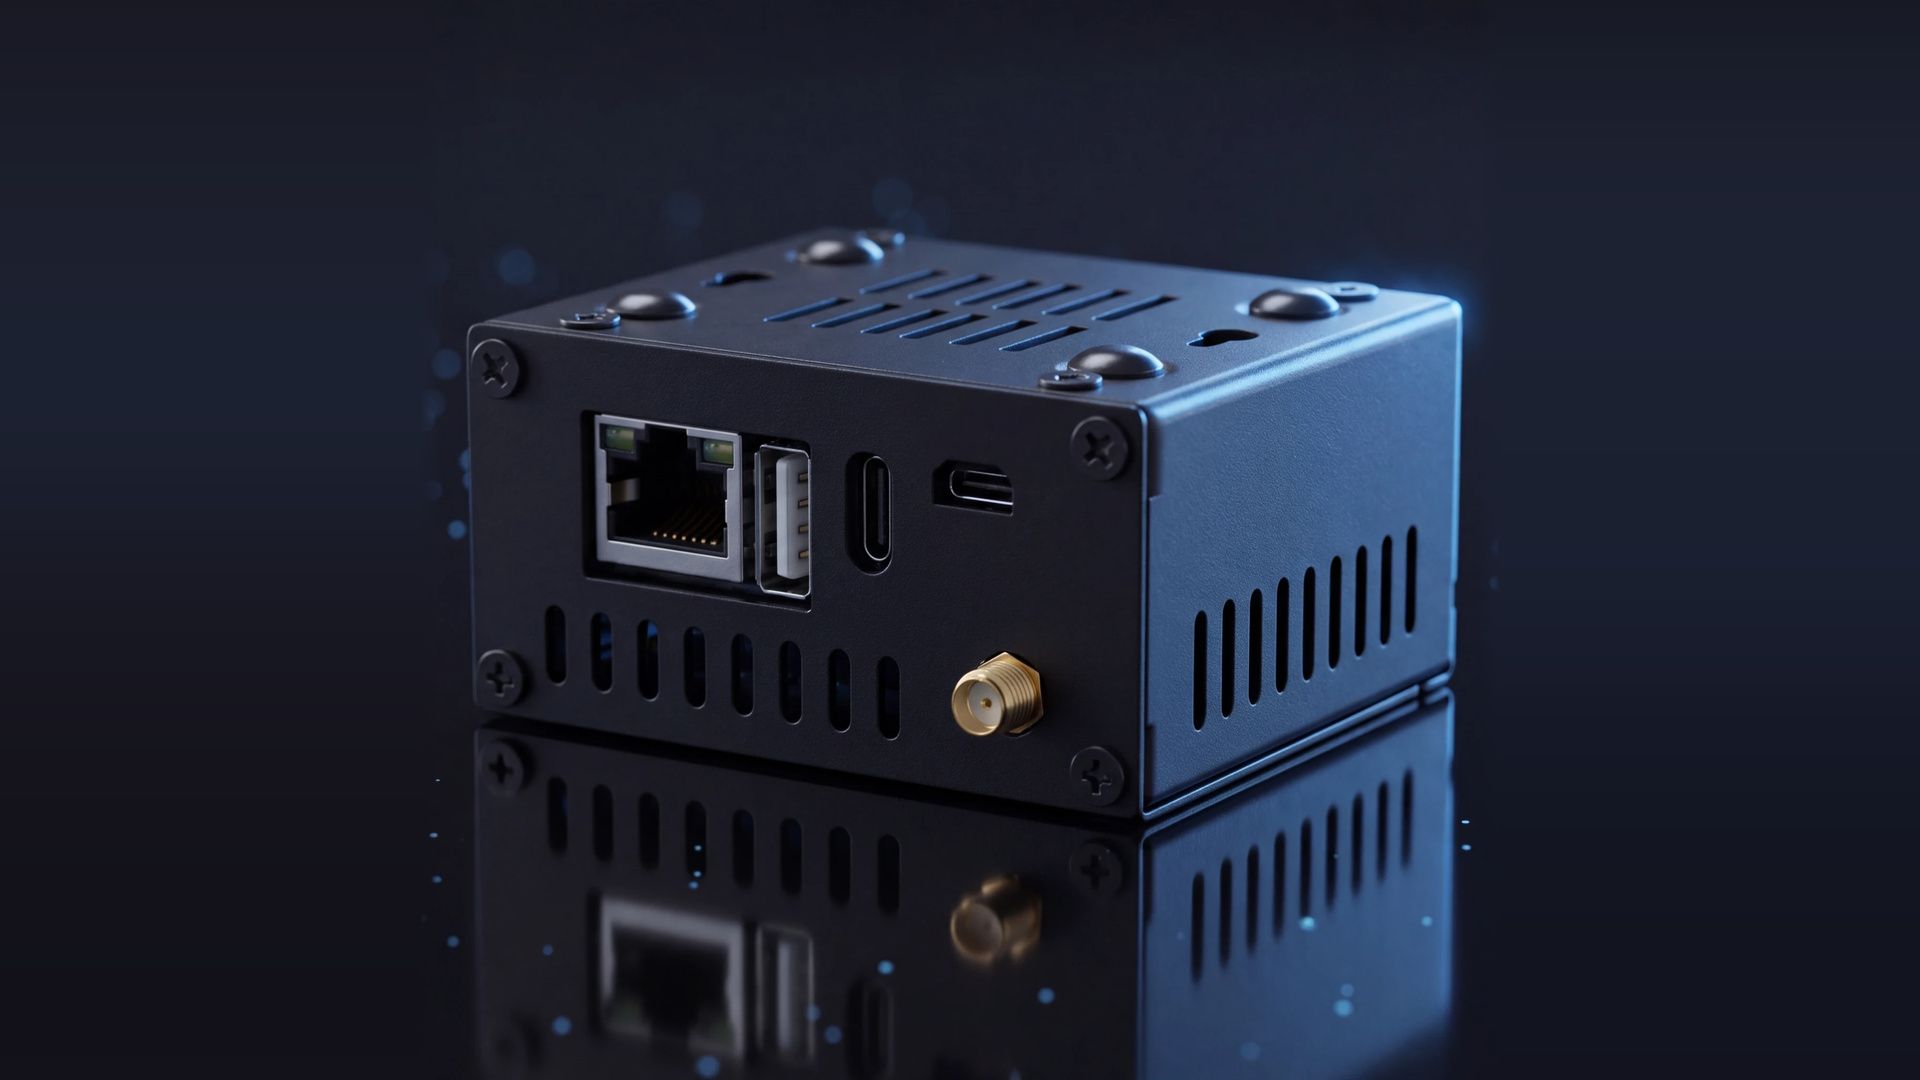
- TradeMAV’s RAMDeck hub is crowdfunding on Indiegogo, listed at $109 for early backers
- The engine underneath is llama.cpp’s RPC backend, which anyone can already run at no cost
- Its fastest demos lean on an RTX 3060 and mixture-of-experts models, while denser models manage around two tokens per second
With DDR5 now costing roughly five times what it did in mid-2025, a small company called TradeMAV thinks the answer to running bigger AI models at home isn’t buying more RAM, but borrowing the memory already sitting in your other devices.
The argument, which is hard to rule against, is being pitched in the form of RAMDeck, which TradeMAV is crowdfunding on Indiegogo, a small, low-power hub that links Windows PCs, Macs, Linux machines and Android phones on a home network into one memory pool, so a model too large for any single device can be split across all of them.
The campaign uses fixed funding against a $10,000 goal and closes on November 8 2026, 2026, according to the company’s launch video, while a cost comparison table in TradeMAV’s own RAM pooling guide lists the hub at $109 as an early-bird reward.
An old trick in a new box?
The timing is interesting, to say the least: German retail data from 3DCenter show DDR5 at 486% of its July 2025 price by mid-August; Samsung has told analysts the shortage will persist through 2028; and SK Group’s chairman has warned it could run until 2030.
All of this creates a perfect storm, and TradeMAV acknowledges it; its origin story leans on the same squeeze, claiming a 64GB DDR5 kit went from about $191 in August 2025 to $1,118 a year later. That broadly matches our own findings that average 2x32GB DDR5-5600 kit prices roughly quadrupled to around $800 in the last quarter of 2025 alone.
What RAMDeck actually does is less exotic than “pooling RAM” suggests. Nothing is merged at the hardware level. Instead, the model’s layers are divided among machines, each holding its share in local memory, and only intermediate results pass across the network as each token is generated.
TradeMAV’s public GitHub repository is candid about the plumbing involved: The node agent starts llama.cpp’s ggml RPC server on each contributing device; the README says any compatible coordinator can drive it over the standard llama.cpp RPC protocol, and the suggested way to confirm it works is a stock llama-cli command.
TradeMAV’s contribution is the orchestration wrapped around it: automatic discovery, layer placement that fills fast GPUs before slower system RAM, failure recovery, a dashboard, and an OpenAI-compatible API, according to its features page.
While the process is detailed, the hub’s other components lack detail; none of TradeMAV’s published pages list its processor, memory, ports, or power draw. Its own pooling guide concedes that if you’re comfortable with terminal scripts, “the free open-
Pooling devices for inference isn’t new. Exo Labs’ open across computers, phones, and single-board computers since at least early 2025. At the premium end, Apple’s new M5 Ultra Mac Studio supports clustering over Thunderbolt 5 with RDMA, and Apple claims four machines deliver up to three times the inference speed of one
RAMDeck’s distinguishing pitch is breadth – its FAQ promises a Windows CUDA desktop, an Apple Silicon Mac, an old Intel Mac, a Linux box and an Android phone in the same cluster, something llama.cpp’s mix of backends makes possible.
TradeMAV is unusually frank about the performance trade-off versus something like a Mac Studio configuration. Its story page warns that “pooled memory trades speed for capacity,” and its benchmark write-up tells readers chasing raw performance to buy a higher VRAM GPU instead.
The headline results lean on a Beelink mini PC with an RTX 3060 and on mixture-of-experts models that activate only around 3 billion parameters per token: 39 tokens per second for Qwen3-Coder 30B across the mini PC and an M4 Mac mini, and 16 tokens per second for a 40B REAP variant of Qwen3-Coder-Next. A 7B model hitting 43 tokens per second was, by TradeMAV’s own description, running on the 3060.
Dense models tell a different story: a 27B dense model managed 1.92 tokens per second across four devices, and OpenAI’s gpt-oss-120b ran at 1.37 tokens per second on a six-device cluster. A 120B model on a different five-machine setup reached 3.1 tokens per second, after taking about seven minutes to initialize. That beats an out-of-memory crash, which is TradeMAV’s pitch, but it is extremely slow.
In a nutshell, RAMDeck’s engine wraps free software, the hub’s specifications are undisclosed, and some published figures point to limitations when applying that approach. For tinkerers, llama.cpp’s RPC mode and exo cost nothing to try first. For everyone else, $109 buys convenience and, as with any crowdfunded hardware, a promise rather than a product.
Disclaimer: We do not recommend or endorse any crowdfunding project. All crowdfunding campaigns carry inherent risks, including the possibility of delays, changes, or non-delivery of products. Potential backers should carefully evaluate the details and proceed at their own discretion.
