

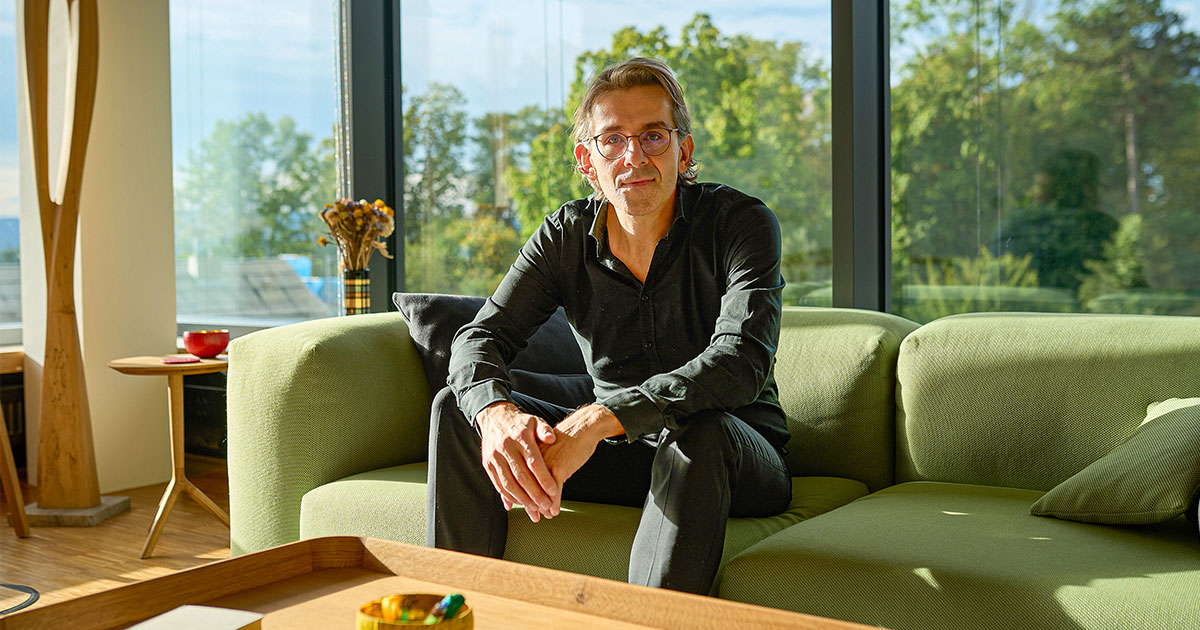
Moritz Hardt, author of a new book on benchmarks, believes these “standardized tests” for artificial intelligence are fundamentally broken — but not unfixable.
Read Later
Introduction
Benchmarks are the rulers of AI, in both senses of the word. As measuring sticks, they work according to an extremely simple logic: If you want to know what an AI model can do, devise a standardized test to gauge it. But AI benchmarks can also dominate the behavior of the entire field.
In 1987, the Defense Advanced Research Projects Agency’s first benchmark on automatic speech-to-text translation showed that state-of-the-art AI could not outperform so-called “dumb” statistical approaches. The poor performance helped to usher in an AI winter. For 25 years, interest in AI research waned and funding dried up.
Then, in 2012, another benchmark called ImageNet swung the pendulum back. An eight-layer neural network trounced other algorithms at classifying images and kicked off a “deep learning revolution.”
Nowadays, new AI benchmarks, geared at large language models such as OpenAI’s GPT-6 Astra, get created and solved with clockwork regularity, purporting to measure everything from domain-specific expertise to “general intelligence.” But rather than hail this trend as proof of AI’s skyrocketing potential, many in the field — skeptics and boosters alike — take it as evidence that benchmarking itself has become fatally flawed.
Moritz Hardt, a computer scientist and a director at the Max Planck Institute for Intelligent Systems, agrees with this diagnosis. Shortly after the ImageNet result, he began to think that machine learning systems could game leaderboards “without doing anything intelligent.” “There’s no two ways about it,” he said. “The benchmarking ecosystem is broken.”
In his 2026 book The Emerging Science of Machine Learning Benchmarks, Hardt makes the provocative case that these measuring sticks have been broken for decades already: Benchmarks, he writes, are “the mistake that made machine learning.” Notably, he argues, instead of creating a replicability crisis, they drove legitimate progress anyway — “mostly by sheer luck,” in his view. By understanding why, we can explain how benchmarks have since lost this accidental credibility in the age of LLMs, and how they might regain it.
Quantaspoke to Hardt about what went wrong, and right, with benchmarks, and where to take them next. The interview has been condensed and edited for clarity.
Let’s get the basics straight: What even is a benchmark?
The recipe is simple. To evaluate a machine learning model, you take your data and split it into a training set and a test set. You let the model builders do whatever they want on the training set: Anything goes, no rules. But you use the test set only to compare and rank models — to have a leaderboard say, “This is currently state-of-the-art, this is number one, this is number two.”
So a benchmark for a large language model today, like GPT-6 Astra or Claude Fable, might test an ability tosolve difficult math problemsorfind security bugs in software.
Right. The first benchmark, in fact, was created in 1959. It was a set of digits and letters printed on punch cards, meant to test how well different scanners could recognize written characters. Somebody introduced the train-test split and started a leaderboard.
It wasn’t like there was some master plan. But that’s what we now call benchmarking, and it’s been the engine of progress in AI for about 60 years or so.
What are benchmarks supposed to tell us?
Traditionally, a benchmark is supposed to be like a thermometer. People train a model to do something, and then you come up with some kind of measurement procedure to see how good the model is.
But in practice, benchmarking is more like a sports competition or a market. Benchmarks define the rules of the game, and people actively compete over them, and we let the best model win.
Jerrit Peinelt for Quanta Magazine
Can’t they be both? What’s the problem?
Any machine learning textbook will tell you about the “holdout method” — that you should lock away the test set, and only use it once to rank the models. If you ignore this, you’re on thin ice. You might get very misleading results because you’re evaluating models that in some sense have knowledge of the test set.
The fascinating thing is that machine learning as a discipline just ignored the warning. It took all these test sets and put them on the internet for everyone to use. It’s easy to put these test sets in a model’s development loop and to keep iterating on them.
Is that what’s “broken” about benchmarks?
If you look at a model’s accuracy numbers on one benchmark, and then you change the test set only slightly, you get completely different accuracy numbers. That’s the sense in which the benchmark is not working. If you have 90% accuracy on one dataset and 73% on another, which is it? I have no idea how good this model is.
OpenAI, Anthropic, and other technology companies still advertise benchmark numbers as a measurement of their models’ reasoning capabilities. Is that just nonsense?
These scores really get misused. If you say, “On this math benchmark, the model got a 90%, which means that the model is now equivalent to an expert mathematician,” you’re reading something into that number that gives you the wrong takeaway. We should avoid comparisons or conclusions that implicitly require the absolute number to make sense.
Jerrit Peinelt for Quanta Magazine
If the absolute numbers don’t make sense, how do you not end up with a replication crisis?
This is where things get really interesting. If, instead of absolute numbers, you look at rankings — relative comparisons between models — those rankings tend to be very stable across different datasets. And this has been pretty consistent across the history of machine learning. If one model gets 90% on a particular test set, and another model gets 80%, then the 90% model is the model you’d want to use in the real world. It’ll still do better on other datasets, even ones that are quite different than the test set.
That, to me, is the main reason why machine learning escaped a scientific crisis.
That’s surprising. So the 90% score doesn’t have much validity, but the fact that it “won” the competition does?
Yeah. So benchmarks tell you when you beat the previous best. And these improvement indicators are pretty reliable.
But it’s lucky that it worked as well as it did — we had no reason to expect this to be the case. And we don’t yet have a good comprehensive theory for why this happens. It’s mostly an empirical phenomenon.
But you also argue that now, in the era of large language models, benchmarks are no longer able to deliver this “accidental” reliability. Why not?
The stability of model rankings has one big caveat: Models need to train on the same training set. In the old days, this was always true. But we don’t know what LLMs were trained on. In fact, model builders can strategically assemble data mixes that best promote benchmark performance. It’s a little bit like studying to the test, which we all do in high school.
That’s why we’re currently in this benchmarking crisis — because it’s no longer true that the better model necessarily wins. A worse model might just put more effort into preparing for the specific benchmark.
This isn’t really a crime: It happens every time a new model is released. If you look at the notes on the latest version of Gemini or GPT, you’ll see that its performance on benchmarks that were released before the new model is often fantastic, while its performance on benchmarks released shortly after is way lower. That’s always an indication that the model was “post-trained” on the earlier benchmark — what some people call “benchmaxxed.” And it’s generally accepted.
Jerrit Peinelt for Quanta Magazine
Is there a way out of this benchmarking crisis, as you call it?
Let me tell you a story: At the 1968 Olympics in Mexico City, there was an American runner who was vastly favored to win the 1,500-meter race. He lost unexpectedly to a runner from the Kenyan highlands, by a wide margin. The Kenyan runner had trained at high elevation and was better prepared for competing at 7,500 feet above sea level. It caused some controversy: Should we outlaw altitude training? The consensus in the end was, just let everyone do it.
The problem is not so much that people optimize to the benchmarks — it’s that they optimize to different degrees. If everyone optimizes, or “altitude trains,” the absolute numbers will be inflated, but you can restore the validity of the rankings.
What would altitude training for AI benchmarks look like?
We don’t know ahead of time what went into these models, but we can train them for a little bit on benchmark-relevant data, just to make sure that we’re leveling the playing field somewhat.
In this new view of benchmarks, you would have no training set. You would have a test set, and you would also have some kind of protocol for preparing each of the models before you test them — that’s the altitude training.
But even if this works, we’re just back to where we started: progress indicators, but no valid measurements. Without that, how can we learn anything about how the models work?
This is a really interesting question. There’s something sad to the triumph of benchmarking, because it seems like we’re giving up what science is actually about: understanding the mechanisms. But if we had some kind of grand mathematical theory to build these models with, we wouldn’t need the benchmarks.
We don’t know how these models do it, and benchmarking won’t tell us.
But benchmarking can, in the long run, lead to new scientific knowledge. The CASP protein-folding benchmark advanced science without first insisting on a scientific theory of protein folding. That’s the paradoxical power of benchmarking in the sciences.
Also in Computer Science
Is ‘Attention’ the Essence of Intelligence?
October 12, 2026
Read Later
As AI Closed In on ‘Unique Games’ Proof, Researchers Raced to Beat the Machines
As AI Closed In on ‘Unique Games’ Proof, Researchers Raced to Beat the Machines
October 7, 2026
Read Later
The Four-Color Theorem Gets a Rare New Proof
The Four-Color Theorem Gets a Rare New Proof
Next article
How Do Fungi Keep the Planet Healthy?
