

Every time anyone builds ML models, the focus quickly moves from overall numbers and highly technical measures of model health to how confident we are in each predicted result. In essence, can my model reliably deliver accurate results across the board? Aggregate metrics such as accuracy, recall, precision, R2, and AUPRC/AUROC are often not enough to convince stakeholders of a model’s real-world performance — no matter how carefully they are explained.
This is where Conformal prediction (CP)could help. In addition to a prediction, CP creates an interval around the prediction that quantifies uncertainty. Such uncertainty quantification through prediction intervals bridges the gap between technical measures of model performance and stakeholder trust. This makes conversations about model reliability far easier than relying on overall model health. For a detailed explanation of the math, see Vovk, Gammerman, & Shafer, 2005. For a more accessible overview, check out Angelopoulos & Bates, 2022. Dancker, 2024 explains CP clearly, and Allen, 2023 offers a helpful Python code walkthrough.
The CP algorithm is an intuitive idea that is flexible across different predictive models(regression, boosting/bagging models, neural networks, etc.) and easy to apply without the help of any specialized machine learning packages. The CP algorithm wraps a statistical processaround a predictive model to generate prediction intervalaround each predicted value. Intuitively, the value of applying CP is therefore to address the problem of reliability of predictions — a probability of customer purchase of 77% is great, but what if this probability can be as low as 50% and as high as 97% — such a wide band around the predicted probability makes the prediction less reliable, versus saying the predicted probability will still be between 70% and 85%.
You might be wondering why CP and why not other well-known uncertainty quantification methods such as bootstrapping or dropout methods used for quantifying uncertainty in neural networks? There are three main reasons:
1) CP does not require any particular model specificationand works quite well for black-box models
2) It is computationally very cheap, especially when compared to bootstrapping, which relies on repeated resampling; and
3) Exchangeability:According toVovk, Gammerman, & Shafer, 1999, exchangeability ensures that calibration (used to compute the prediction interval) and test points (used to test the computed prediction interval) can be treated as if they come from the same distribution. As a result, the prediction intervals computed on the calibration set provide a valid coverage guarantee. If α proportion of calibration points fall outside the interval (and 1−α are inside) for the calibration set on average, then the same coverage level holds for the test points on average.
With these in mind, let’s walk through the algorithm using the publicly available Online Shoppers Purchasing Intention Dataset(Sakar & Kastro, 2018). This dataset is available in the UCI Machine Learning repository and is licensed under Creative Commons Attribution 4.0 International (CC BY 4.0) license, which permits commercial use. It is quite appropriate for this example at hand, as it is a typical dataset for customer purchase prediction.
First, let’s start with all the basic packages that we need for this exercise.
# Import all the required packagesimport pandas as pdimport numpy as npimport matplotlib.pyplot as pltimport seaborn as snsfrom sklearn.model_selection import train_test_splitimport xgboost as xgbfrom sklearn.metrics.pairwise import euclidean_distancesNext up, we load the Shoppers Purchase Intent Dataset. For some reason, I couldn’t make the API call work, so I went to the UCI Machine Learning Repository and downloaded the CSV file instead.
# Load online shoppers datasetdf = pd.read_csv("online_shoppers_intention.csv")# Features and targetX = df.drop("Revenue", axis=1)y = df["Revenue"].astype(int)# Convert string columns to categorical dtype (for Month and VisitorType)X_encoded = pd.get_dummies(X, drop_first=True)The CP algorithm needs the data split into three parts:
-
Train setto learn a model (e.g., classifier, neural network, etc.)
-
Calibration setto quantify the model’s uncertainty through conformal scores that enable the development of prediction intervals (more of this in a little bit)
-
Test set to evaluate the reliability of the model and its uncertainty quantification.
The above is achieved through a 70%/15%/15% split between the train/calibration/test sets:
# Split into 70% train and 30% temporary datasetX_train, X_temp, y_train, y_temp = train_test_split(X_encoded, y, test_size=0.3, random_state=42, stratify=y)# Split the 30% temporary dataset into 15% calibration and 15% testX_cal, X_test, y_cal, y_test = train_test_split(X_temp, y_temp, test_size=0.5, random_state=42, stratify=y_temp)Given this sample design, let’s do this in a step-by-step fashion:
Step 1: Train the model
I begin by training an XGBoost model to the online purchase intent dataset to understand the impact of all available features on the probability of purchase (Revenue=1 indicating the user session resulted in an e-commerce purchase and 0 indicating lack of purchase). For a parsimonious representation of the CP algorithm, I don’t do any additional feature engineering in this article.
Before modeling, let’s first see the distribution of the Revenuevariable to determine whether we have any class imbalance.
# Calculate counts and percentages for the outcomecounts = y.value_counts()percentages = y.value_counts(normalize=True) * 100# Create the bar plotplt.figure(figsize=(6, 4))sns.countplot(x=y, palette="Set2")# Add titles and labelsplt.title("Target Variable (Revenue) Class Distribution", fontsize=14)plt.xlabel("Class (0 = False, 1 = True)", fontsize=12)plt.ylabel("Count", fontsize=12)plt.xticks(ticks=[0, 1], labels=[f"0 ({percentages[0]:.1f}%)", f"1 ({percentages[1]:.1f}%)"])plt.tight_layout()plt.show()
Based on the distribution of the 1’s and 0’s in the Revenuevariable shown in Figure 1, only 15% of the data points belong to the positive class (=1). We therefore need imbalance treatment. Again, for the sake of parsimonious representation, I use weighted XGBoost, although we could do a more rigorous selection with other methods like SMOTE and Random Undersampling too.
# Weighted XGBoostpos = sum(y_train == 1)neg = sum(y_train == 0)scale = neg/pos# Define the modelmodel_weighted = xgb.XGBClassifier(n_estimators=200,max_depth=5,learning_rate=0.05,subsample=0.8,colsample_bytree=0.8,use_label_encoder=False,eval_metric="logloss",scale_pos_weight=scale)# Train the model on training setmodel_weighted.fit(X_train, y_train)Now that we have fit the model, let’s see the top 10 features by importance
xgb.plot_importance(model_weighted, max_num_features=10, importance_type="gain")plt.title("Top 10 Features by Importance (XGBoost)")plt.show()
Intuitively, the feature importance makes sense. For example, the number of times the customer visited the webpage (PageValues) is clearly the most important indicator of purchase decision, followed by the month of purchase (e.g., Nov could be driven by the ThanksGiving break). Similarly, customers often visit the product page multiple times before making the decision; hence, VisitorType_Returning_Visitoralso showing up there makes sense.
With the trained model in place, lets turn to calibrating its uncertainty.
Step 2: Calibrate the model
Calibration helps us measure how far predictions are from reality, and build prediction intervals around them. It consists of four parts.
-
Predict probabilities on the calibration set p(x)
-
Compute conformal scores, i.e., how far or close the predicted probability p (x) isto the true label (y). It can take several functional forms; I choose a simple and intutitive one: |y-p(x)|,where y is the true label (1 or 0).This ensures that the larger the score, the farther away it is from the true label. You can do a mental math with a few examples to see this yourself. There certainly are other options that can measure the conformal score, such as inverse probability weights, normalized residuals, etc. Again, for considerations of parsimony, I choose the absolute residuals here.
-
Choose an acceptable error tolerance α. Think of αas the proportion of observations we are willing to accept will fall outside the prediction interval that we will go on to compute. Let’s say it’s α = 30%. This will mean that 30% of the predictions will fall outside the prediction interval. If we flip this argument, it means that the prediction interval will contain at least 70% of the true labels.
-
Find the 1-α percentile value (70th percentile) of the conformal scores from above to obtain the conformal quantile (q).We can also refer to this as prediction interval,which we use to develop confidence bands around predicted probabilities on the test data
I explain this with a simplistic example in table 1 below. For each of the customers, we calculated the predicted probability of purchase as well as the conformal score based on the difference with the true label (last column). If we sort the conformal score in ascending order: [0.1,0.2,0.25,0.35,0.4], the 70th percentile score would be 0.35 → the conformal quantile.

Here is the chunk of code that predicts the probabilities and computes the conformal scores and conformal quantile on the calibration set.
# Calibration stepp_cal = model_weighted.predict_proba(X_cal)[:, 1]scores = np.abs(y_cal - p_cal)alpha = 0.3 # Can we changed by the us based on acceptable toleranceq = np.quantile(scores, 1 - alpha) # Identified conformal quantileCalibration gives us a quantile-based intervalthat helps us determine how reliable the predictions will be on unseen (test) data, which is what we do in the next section.
Step 3: Apply to the test set
Step 3.a: Fixed interval approach
First, we use the calibration data derived conformal quantile in step 2 on predicted probabilities on the test set to generate prediction intervals. As seen in the previous step, the conformal quantile was 0.35. I again draw upon a hypothetical example illustrated in table 2 below to develop the prediction interval using predicted probabilities and conformal quantile.
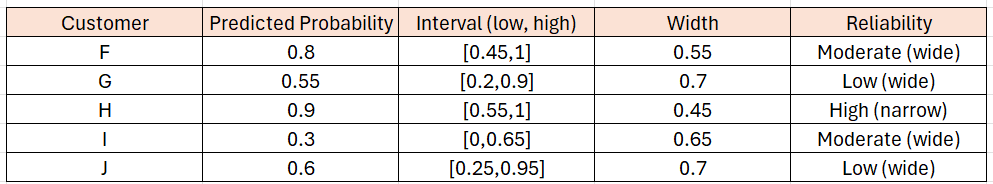
As you can see through this dummy example, customer F has a high predicted probability of purchase (80%) but with a moderately wide prediction interval. This would make it a less reliable prediction when compared with customer H, which has a high predicted probability (90%) as well as a narrow prediction interval.
Notice that I had to clip the intervals to 0 and 1, as we are dealing with a binary classification model, so the lowest and highest probabilities cannot go beyond 0 and 1, respectively.
Below is the code chunk to apply this to the test set and develop prediction interval around the predictions.
# Apply basic conformal prediction to test setp_test = model_weighted.predict_proba(X_test)[:, 1]# Extract the prediction interval based on the identified quantileintervals_const = np.vstack([np.clip(p_test - q, 0, 1),np.clip(p_test + q, 0, 1)]).TThe purpose behind this exercise is to examine if each prediction has a different prediction interval around it. So, let’s plot each test set data point to see if the prediction interval varies for them in figure 3.
# Order the test data points from lowest to highest predicted probabilityorder = np.argsort(p_test)p_sorted = p_test[order]intervals_sorted = intervals_const[order]# # Plot predicted probabilitiesplt.figure(figsize=(10,6))plt.plot(p_sorted, color="blue", label="Predicted probability on test data")plt.fill_between(np.arange(len(p_sorted)),intervals_sorted[:,0], intervals_sorted[:,1],color="gray", alpha=0.3, label="Prediction interval")plt.xlabel("Test data point index")plt.ylabel("Probability of class 1")plt.legend()plt.show()
Note that this is a naïve version of the prediction interval — the variance in interval across test data points is due to the clipping at 0 and 1 — in theory, this would have been equal to 2qwithout clipping. However, in spirit, this nearly equal prediction interval around each test data point does not help our original problem, which is that each predicted point has a varying level of reliability or confidence. Next, I present an extension of this approach which considers locally adaptive intervals.
Step 3.b: Adaptive interval approach
Instead of using a fixed prediction interval drawn from the calibration sample, I will weigh each calibration point based on its similarity to each test data point. Therefore, if x represents the set of features of the test data point, and x’represents the features for the ith calibration set, then we can compute the distance between them. Let’s use the Gaussian Kernel (Bishop, 2006) defined below to determine a Euclidean distance, although many other distance measures could have been alternatively utilized here. Let me also take σ as the 25th percentile of the calculated distance. The smaller σ, the more adaptive your weights are to variation in the calibration data points.

Let’s consider a simple example with one variable, PageValuesand an illustrative set of customer data points shown in table 3. Suppose we have a test datapoint where PageValues=45 and the predicted probability is 0.75. For a set of three customers in the calibration set, with data on their PageValues (Second column) as well as computed conformal scores (third column). Let’s say the σ was 10. We set out to calculate the Euclidean distance. For each of the three customers, the raw distance to the test data point would be (45–20=25), (45–40=5), and (45–60=15). Using the formula above, we can estimate a raw weight of 0.044, 0.882, and 0.324 for each data point. If we normalize these weights with their sum (~1.25), we get the normalized weights in the last column. Naturally, PageValues of 45 are closest to customer B, which gets 71% of the weight, and farthest from customer A, which gets 4% of the weight.
For simplicity, I took only one feature (i.e., the PageValues) for this example. Still, the Euclidean function can take in all the features in the data to compute the pointwise distances.

Next, if we calculate the cumulative weight by the sorted conformal scores, then it would be customer A → 0.04, customer B → 0.75 (0.04 + 0.71), and customer C → 1 (0.04 + 0.71 + 0.26). Again, with α = 30%, the 1-αpercentile is the smallest score with cumulative weight greater than or equal to 1-α (=70%).This would therefore be 0.2. So the prediction interval for this particular test data point would be 0.2. If we repeat this process for each test data point, we will get a prediction interval that is adaptive to that test data point in terms of its similarity with the calibration data, rather than a single standard quantile that we estimated before.
The chunk of code below would build the adaptive prediction interval for each of the test data points:
# Test to calibration distancesdist = euclidean_distances(np.array(X_test), np.array(X_cal))# Sigmasigma = np.percentile(dist, 25)# Compute q for each test pointq_local = []for i in range(len(X_test)):d = dist[i].ravel() # distances to calibration pointsw = np.exp(-d**2 / (2 * sigma**2))w = w / w.sum()# convert scores to NumPyscores_np = np.array(scores)# sort scores and weights togetheridx = np.argsort(scores_np)scores_sorted = scores_np[idx]weights_sorted = w[idx]# cumulative weightscum_weights = np.cumsum(weights_sorted)# cutoff for weighted quantilecutoff = (1 - alpha) * weights_sorted.sum()q_i = scores_sorted[cum_weights >= cutoff][0]q_local.append(q_i)q_local = np.array(q_local)# Build adaptive intervalsintervals_adaptive = np.vstack([np.clip(p_test - q_local, 0, 1),np.clip(p_test + q_local, 0, 1)]).TSimilar to the fixed prediction interval chart, if we are to plot these to get a visual sense of the variability of each prediction, we can do this:
# Sort test predictions and intervals by predicted probabilityorder = np.argsort(p_test)p_sorted = p_test[order]intervals_sorted = intervals_adaptive[order]# Plot predicted probabilitiesplt.figure(figsize=(10,6))plt.plot(p_sorted, color="blue", label="Predicted probability on test data")plt.fill_between(np.arange(len(p_sorted)),intervals_sorted[:,0], intervals_sorted[:,1],color="gray", alpha=0.3, label="Kernel-weighted prediction interval")plt.xlabel("Test data point index")plt.ylabel("Probability of class 1")plt.title("Kernel-weighted Prediction interval")plt.legend()plt.show()
As you can see in figure 4, the significant number of spikes indicates that we are adapting the prediction interval to each data point in the test set.
Step 4: Putting this all together for reliable predictions
Let’s get down to estimating the number of customers who are likely to make a purchase. Suppose we think of a 70% predicted probability of purchase as a reasonable cut-off to differentiate likely purchasers from non-purchasers.
# Test points with predicted probability greater than 70%mask_highprob = p_test >= 0.7p_high = p_test[mask_highprob]p_low = p_test[~mask_highprob]# Define datalabels = ["Likely to Purchase", "Not likely to purchase"]counts = [len(p_high), len(p_low)]# Bar plotplt.figure(figsize=(6,5))bars = plt.bar(labels, counts, color=["green", "red"], alpha=0.7)for bar in bars:height = bar.get_height()plt.text(bar.get_x() + bar.get_width()/2.0, height, f'n = {height}',ha='center', va='bottom', fontsize=10, fontweight='bold')plt.ylabel("Number of customers")plt.title("Number of customers likely to purchase")plt.show()
As we can see in figure 5, 305 customers out of 1850 (=16.5%) are what the model predicts would be the likely purchasers. But are thesereliableestimates?
To answer this question, I first look at the prediction interval that we have created for each predicted test data point. Specifically, I try to understand how much the prediction interval (i.e., difference between the upper and lower quantile) of each predicted point varies across the actual predicted probability.
# Build DataFramedf = pd.DataFrame({"p_test": p_test,"low": intervals_adaptive[:,0],"high": intervals_adaptive[:,1]})# Create a copy of the datasetdf_class1 = df.copy()# Interval widthdf_class1["width"] = df_class1["high"] - df_class1["low"]# Scatter plotplt.figure(figsize=(8,6))plt.scatter(df_class1["p_test"], df_class1["width"], alpha=0.1, color="purple")plt.xlabel("Predicted probability (class 1)")plt.ylabel("Prediction interval")plt.title("Correlation between predicted probability and interval width")plt.show()
Figure 6 indicates that, on average, the prediction interval keeps increasing until we reach the 50% mark and then decreases again. This behavior is expected, as predictions at the extreme ends of the spectrum will likely have a clear reason for being there. Naturally, the prediction interval would be narrower as the model is confident in predicting clear-cut cases of 1 or 0. It’s the middle portion, where it could go either way, that the model’s prediction interval also increases (and reliability decreases).
However, the important thing to note is that for then=305 data points with predicted probability greater than 70%, the prediction interval can vary widely, as shown below in figure 7.
# Count total observations above threshold probabilitydf_class2 = df_class1[df_class1['p_test'] >= 0.7]num_obs = len(df_class2)# Create the histogramax = df_class2['width'].hist()ax.set_title(f'Distribution of prediction interval for likely purchasers (n = {num_obs})')ax.set_xlabel('Prediction interval')ax.set_ylabel('Frequency')# Add counts on top of each barfor rect in ax.patches:height = rect.get_height()if height > 0:ax.annotate(f'{int(height)}',xy=(rect.get_x() + rect.get_width() / 2, height),xytext=(0, 5),textcoords="offset points",ha='center', va='bottom')# Add a vertical red line at x = 0.3ax.axvline(x=0.3, color='red', linestyle='--', linewidth=2, label='Prediction interval= 30%')ax.legend()plt.show()
There could be two approaches to choose the most reliable predictions:
-
Option A: The bounds of prediction should be within certain percentage of the prediction itself. Suppose the prediction is 80% and we want the prediction width to be within 30% of this prediction. So, we consider a prediction to be reliable if its bound is > 56% and upper bound is less than or equal to <104%. This would qualify 174 observations out of the 305 likely purchasers as reliable(=57%).
# Predictions with the width within certain bounds of the predicted valuewithin_30pct = len(df_class2[(df_class2['low'] >= df_class2['p_test'] * 0.70) &(df_class2['high'] <= df_class2['p_test'] * 1.30)])# Print the resultprint(f"Number of data points where bounds are within 30% of p_test: {within_30pct}")
-
Option B: The prediction width is within a certain cut-off, let’s say 30% → i.e., any likely purchaser whose prediction interval width is less than or equal to 30% is considered reliable. In this case, this would qualify 129 observations out of the 305 likely purchasers as reliable(=37.4%).
# Predictions with prediction width within a certain valueless_than_30_pc = len(df_class2[df_class2['width'] <= 0.3])print(f"Number of observations with width <= 30%: {less_than_30_pc}")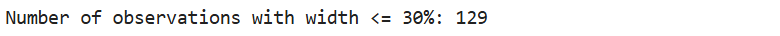
-
Option C: Prediction width must within a certain threshold of the predicted probability. Let’s say we continue to consider a width threshold of 30%. If we consider a predicted probability of 80%, then the width should not exceed 24%. In this case, this would qualify 103 observations out of the 305 likely purchasers as reliable(=29.9%).
# All observations within 30% of each test point predictionwithin_30_pc_pred = len(df_class2[df_class2['width'] <= (0.30 * df_class2['p_test'])])print(f"Number of points where width is at most 30% of p_test: {within_30_pc_pred}")
Conclusion
As you can see, the CP algorithm gives us the added comfort of choosing reliable predictions based on user-defined thresholds that can be widely (and quite easily) applied to most prediction use cases. It tells us how much we can trust each prediction without relying only on the overall model health. From a practical standpoint, this can be a great add-on to the ML model that enables building stakeholder trust. Such visibility also increases the actionability of machine learning models. The adaptive method could be an especially useful toolkit for data scientists, although it may not carry the formal coverage guarantee.
As discussed earlier in the introduction, this is not the only method to quantify model uncertainty. Depending on the data and context, other methods might suit better. The results shown are experiments, rather than proof of mathematical guarantees of the CP algorithm. So, please consider this article and the results as a practical guide rather than a definitive take on the subject. Also, this reflects my own learning journey, and if you find mistakes or have suggestions, I would welcome your feedback and thoughts.
Disclaimer: Views are my own and do not reflect those of any employer.
References:
-
Angelopoulos, A. N., & Bates, S. (2022). A gentle introduction to conformal prediction and distribution-free uncertainty quantification. arXiv preprint arXiv:2107.07511v6
-
Bishop, C. M. (2006). Pattern Recognition and Machine Learning. Springer
-
Sakar, S., & Kastro, Y. (2018). Online Shoppers Purchasing Intention Dataset. UCI Machine Learning Repository. https://doi.org/10.24432/C5F88Q. Licensed under CC BY 4.0.
-
Vovk, V., Gammerman, A., & Shafer, G. (2005). Algorithmic learning in a random world. Springer
