

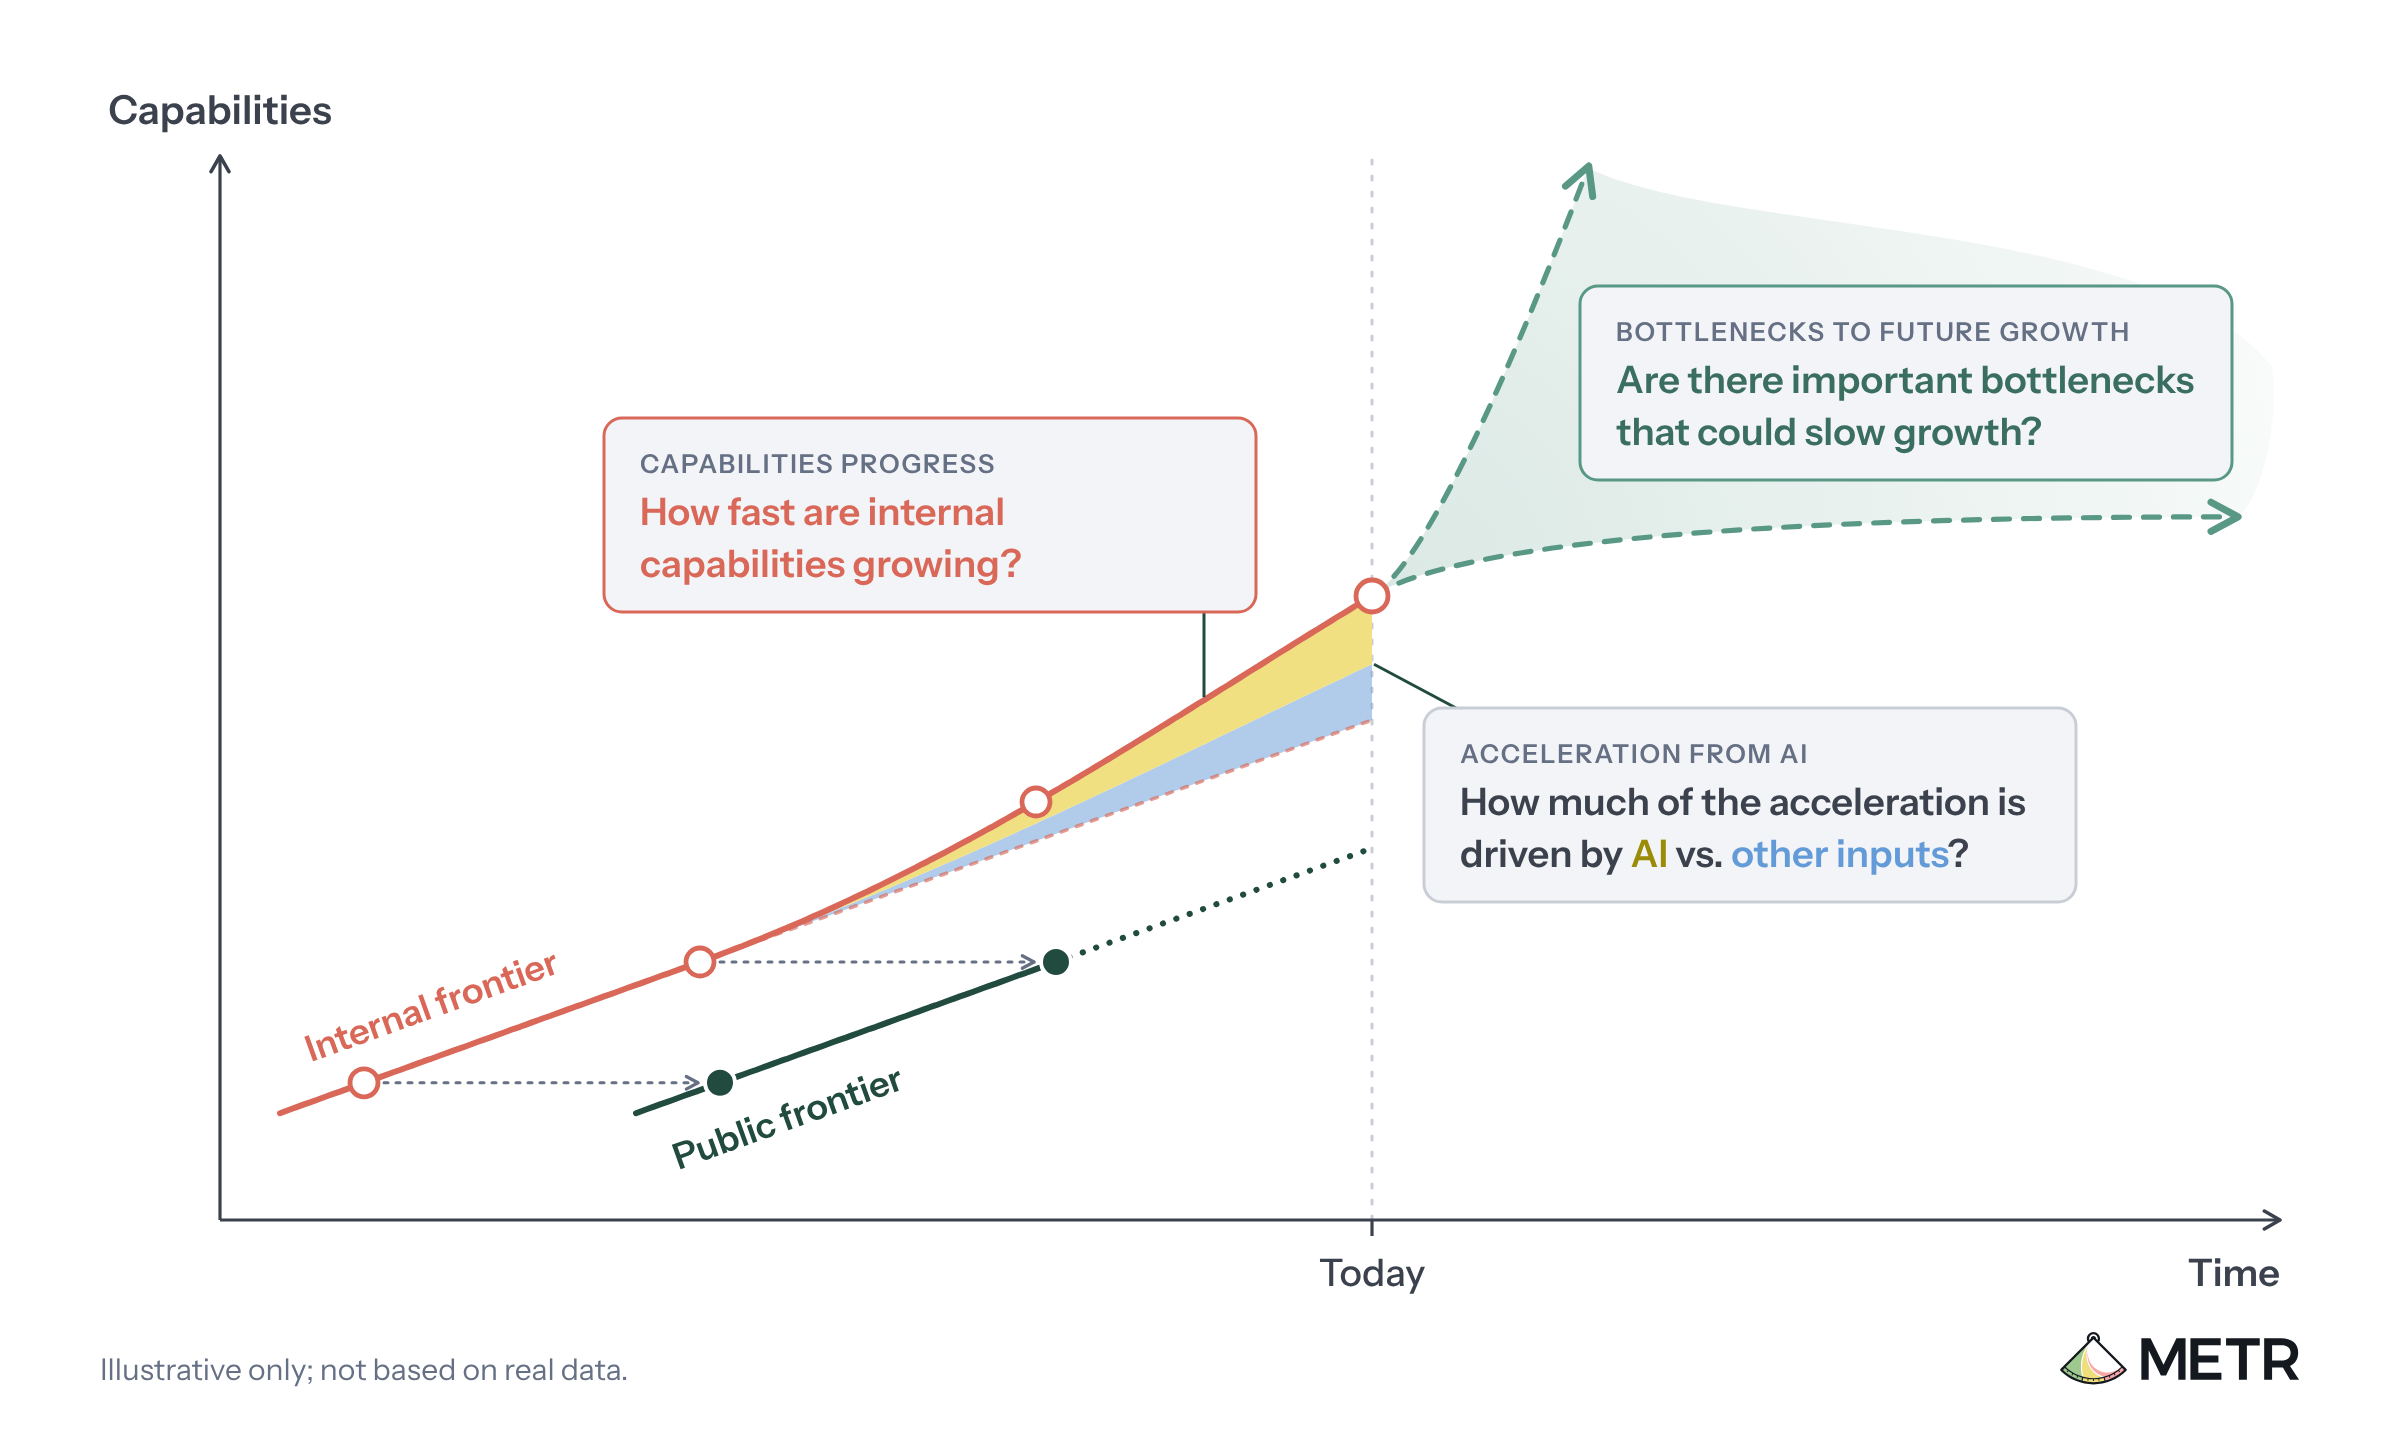
This article discusses how an assessor could study whether capabilities progress could accelerate dramatically due to AI-driven acceleration of AI R&D. Such an assessment would answer:
- Capabilities Progress: How fast are internal capabilities improving, and how much has this progress accelerated recently?
- Acceleration from AI: If there is an acceleration, how much was it driven by AI automation versus other factors?
- Bottlenecks to Future Growth: Are there important bottlenecks that could slow growth or limit acceleration in the near term?
- Limitations: Would these methods reliably identify much more dramatic acceleration if it had occurred?
Assessing this would involve analyzing capabilities of unreleased models, understanding the growth of key AI R&D inputs (labor, compute, data, and algorithms), and talking openly with relevant researchers about how AI is impacting their work. More details on access below.
Scope
Capabilities Progress
To understand whether capabilities progress has accelerated, the assessor must obtain data on internal model capabilities across time. Since AI capabilities cannot be understood through any single approach,1 the assessor must gather data
- Benchmarks: How much has progress on a variety of capability benchmarks (and aggregate measures like ECI) accelerated?
- Intermediates: How much has progress in key intermediate measures or leading indicators (e.g. pretraining loss) accelerated?
- Perceptions: Are researchers who use internal models experiencing an acceleration in model capabilities, as measured by interviews or surveys?
- Other: Are there other proxies that are crucial for understanding the pace of capabilities progress, and what trends do they show?
Acceleration from AI
To understand whether capabilities acceleration is driven by AI, the assessor would need to study the inputs that seem most likely to be affected by AI automation. This means assessing:
- How much of this acceleration in capabilities is due to algorithmic progress or data versus other inputs like scaling compute that are less impacted by AI automation?
- How much of the acceleration in algorithmic progress or data is attributable to AI assistance/automation versus other inputs like experiment compute and labor?
Bottlenecks to Future Growth
The assessor would then examine if there are reasons to expect growth or acceleration to slow in the near future. This requires answering:
- Are there important bottlenecks (e.g. training compute, human data) that could plausibly slow progress in the near future, and how might they impact near-term growth?
Limitations
The assessor would additionally investigate how confident the public should be that a dramatic acceleration would be noticed and communicated if it occurred. This requires answering:
- How reliable are the estimates of internal acceleration and attribution, and what are the biggest concerns with the evidence sources?
- How does the internal evidence studied compare to relevant public evidence about acceleration, and what might explain any differences?
- Overall, would the methods used reliably have identified much greater acceleration, if it had occurred?
Access details
To answer these questions, the assessor requires measurements of inputs and outputs across the model development pipeline. Whenever possible, data should be provided over the maximum possible timeframe and with precise dates on observations to help assessors estimate changes versus a historical baseline. Where relevant, data should be broken down by team or domain, to help assessors connect specific changes in inputs to research outputs.
For security, data could be analyzed on developer hardware (and possibly onsite at developer premises). Only minimal access to developer infrastructure is needed for this assessment.
Measurements of internal capabilities
The assessor would need measurements of internal model capabilities over time to judge if they are accelerating. This includes details on:
- Benchmark data. Scores on all measured benchmarks across all frontier (including internal-only) models, to calculate ECI and other similar measures of progress. For robustness, details on each benchmark should be provided, including example questions and scoring details, and sample answers from models.
- Qualitative/quantitative info from researchers. Existing reflections from researchers (including excerpts from interviews or existing internal surveys) that help summarize how researchers perceive capabilities changing over time. This should be supplemented with assessors interviewing staff directly.
- Top-line progress measures for key domains. Detail on how progress is tracked/measured in pretraining, posttraining, and other key parts of the model development pipeline, along with historical records of progress in each. It may be useful to share details and analysis on how the developer understands key domains drive overall capabilities progress (e.g. how much progress is being driven by pretraining versus posttraining), as it will allow better estimates of how acceleration in key domains will flow through into capabilities acceleration.
- Other internal capability measures. Any other internal measures of capabilities that are tracked should be shared for robustness.
Algorithmic progress estimates
We expect that developers currently maintain some estimates of algorithmic progress in key domains like pretraining and posttraining. While developers have not published details on these methods, they may be similar to the methodology defined in this paper, where research advances are mapped to a reduction in the compute required to reach certain performance levels.
The assessor does not require details of the specific research advances. However, an assessor would require estimates of the effect of these advances over time (dated precisely) and between models. Ideally, algorithmic progress estimates are as disaggregated as possible to allow for flexible analysis.
Evidence of AI’s contribution
As it is challenging to determine the “No AI” counterfactual, we expect that a well-calibrated estimate of AI’s impact on AI R&D will require a number of lines of evidence. We expect that conversations between assessors and researchers could be highly informative in prioritizing specific data required to answer this question, but list a few illustrative examples of informative evidence here:
- Spend on AI agents. This ideally would be broken down by team and over time, denominated in tokens and inference cost.
- Researcher qualitative reflections. Specific stories of how research progress is made using models will provide significant insight into how AI is impacting the AI R&D process.
- Labor productivity estimates. This includes crude metrics like lines of code per researcher-day or self-reported uplift estimates over time.
Measurements of key R&D inputs
Inputs other than AI may drive an acceleration in capabilities2 or algorithmic progress, and so it is important to understand how other key inputs are growing. Adjusting for the effect of other factors requires data on those factors:
- Labor inputs. The size of teams working on key domains, reported over time.
- Compute inputs:
- Training compute. For each model, how much compute was used on pretraining, midtraining, posttraining, etc.
- Experimental compute. Over time, broken down by team and function.
- Data inputs. This is domain specific and may include information about pretraining data or RL environments.
- Other key inputs. If there are other key inputs that are not externally known, those should be shared with assessors as well.
Details of bottlenecks and forecasts
Assessors should be provided with information that allows them to forecast future capabilities and the plausibility of hitting dangerous capability milestones in the near term.
Assessors should ideally be given access to:
- Information on bottlenecks. For possible bottlenecks, assessors should be given detailed evidence on the plausibility of these bottlenecks.
- Existing forecasts. Where they exist, assessors should be able to collect forecasts of top-line metrics and details behind those forecasts.
Forward-looking estimates are highly uncertain and should be treated as such in the resulting report.
To properly contextualize the information above, and to make sure they are not missing anything, assessors must be able to talk directly to researchers.
The assessor would need to interview staff involved in each important part of model training to confirm their understanding of the data, and to understand if there are other important missing sources of data. This would include researchers familiar with pretraining, RL, and infrastructure.
Additional conversations with researchers who have a more holistic view are likely also very helpful to the assessment, for example with researchers who study capability progress or acceleration internally, or with managers responsible for key domains.
-
For example, a naive interpretation of benchmark scores may overestimate model capabilities because passing tests does not directly correspond to real-world usefulness, while quantitative estimates of “speedup” from researchers may overstate capabilities because of the difficulty of assessing the counterfactual. ↩
-
For example, an above-trend compute scaleup might result in above-trend capabilities growth. ↩
